Harnessing Multimodal AI: Integrating Text, Image, Audio, and Video
Learn how to harness multimodal AI for integrating text, image, audio, and video data in various applications.
Get the daily AI & tech briefing.
Understanding Multimodal AI: A Deep Dive into Diverse Data Processing
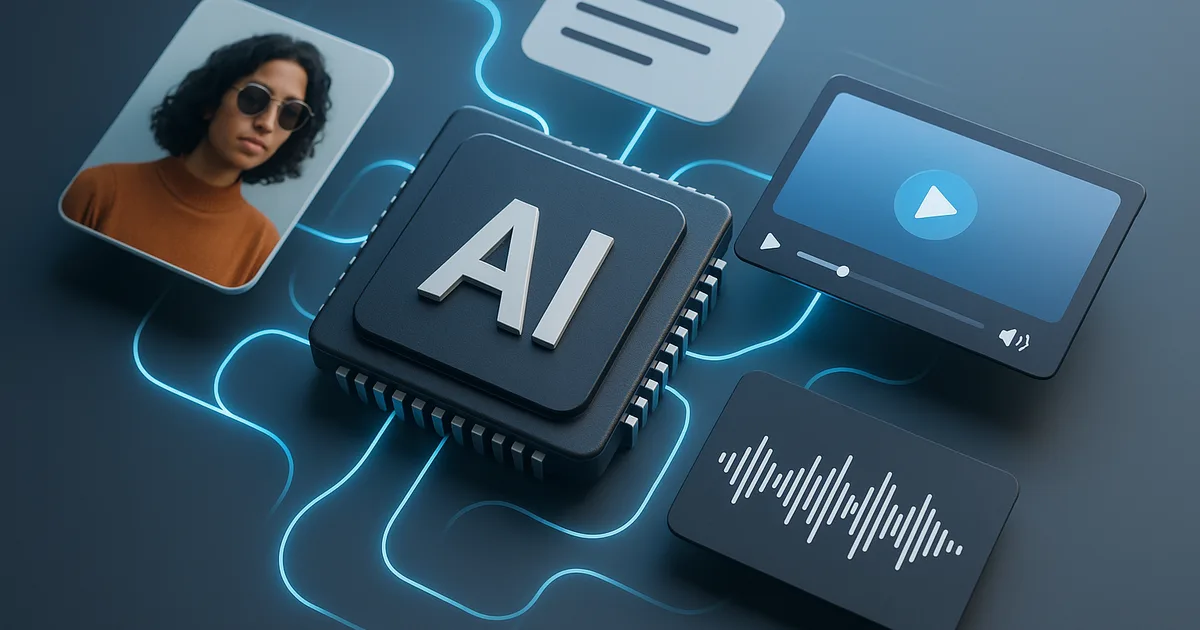
Multimodal AI is transforming the ways we interact with technology by seamlessly integrating various types of data - text, images, audio, and video - into cohesive systems. Unlike unimodal AI, which focuses on a single type of data, multimodal AI brings together different modalities to enhance understanding and create more intelligent applications.
What Is Multimodal AI?
At its core, multimodal AI involves the synchronization of multiple data types to improve analytical capabilities and user interactions. This type of AI can understand and generate data across various formats, making it highly adaptable and versatile. Imagine an AI system that can read a news article, analyze related images, listen to relevant podcast clips, and even watch video segments - all to provide a comprehensive understanding of a subject.
This integration is made possible through sophisticated architectures that combine the strengths of neural networks, natural language processing (NLP), and computer vision, among others. By leveraging these advanced technologies, multimodal AI systems break down the silos between different data types, enabling richer analysis and interaction.
Advancements in Multimodal AI Technology
Recent years have seen significant advancements in the technologies enabling multimodal AI. Innovations in machine learning and deep learning have been pivotal in overcoming the challenges of integrating different data types. For instance, Transformer-based architectures, like OpenAI's GPT-3 and Google's BERT, have revolutionized NLP and provided a foundation for understanding and generating language.
In parallel, developments in computer vision have allowed AI systems to interpret images and videos with higher accuracy. Combined with audio processing advancements, these technologies enable AI models to interact in more human-like ways. The amalgamation of these advancements facilitates the creation of AI models that can seamlessly engage with the diverse data that people encounter daily.
Choosing the Right Multimodal AI Models for Your Needs
Choosing an appropriate multimodal AI model depends on several factors, including the specific application, data types involved, and computational resources. Key considerations include:
- Data Compatibility: Ensure the model supports the modalities you intend to use. Some models are better suited for text and image integration, while others might excel at audio-visual tasks.
- Performance and Accuracy: Evaluate the model's performance metrics, such as accuracy, speed, and scalability, to ensure it meets your application's requirements.
- Scalability: Consider whether the model can scale with your needs. If your data volume is likely to grow, the model should handle increased demand without compromising performance.
- Ease of Integration: Opt for models with comprehensive documentation and community support for smoother implementation and troubleshooting.
For example, choosing the right multimodal AI models for your needs requires understanding these factors deeply to make informed decisions.
Integrating Multimodal AI with Existing Data Pipelines
Incorporating multimodal AI into existing data pipelines requires careful planning. Here's a structured approach:
- Assessment of Current Infrastructure: Evaluate if your current data systems can accommodate the computational requirements of multimodal AI. This might involve upgrading hardware or leveraging cloud solutions.
- Data Preprocessing: Ensure raw data from different modalities are clean and standardized for the AI model to process effectively. Preprocessing steps might vary significantly across text, images, audio, and video.
- Streamlining Workflow: Integrate AI models in a way that aligns with existing workflows to prevent disruptions. Automating data flow between different processing stages can enhance efficiency.
- Continuous Monitoring and Feedback: Establish mechanisms for continuous performance monitoring and user feedback to refine the system and address potential bottlenecks.
Integrating multimodal AI with existing data pipelines effectively ensures that the transition is smooth and sustainable.
Best Practices for Integrating Multimodal AI in Applications
Successfully integrating multimodal AI into applications follows distinct best practices:
- Start With Clear Objectives: Identify the specific problems multimodal AI will solve. Clear objectives guide model selection and integration strategies.
- Iterative Development: Adopt an agile approach. Start small, evaluate results, and then scale progressively, allowing room for testing and improvement.
- User-Centric Design: Consider end-users when designing AI interactions. Tailor AI capabilities to enhance user experience and meet user needs effectively.
- Ethical Considerations: Address ethical concerns such as data privacy and bias. Ensure the multimodal AI operates fairly and transparently, with appropriate safeguards.
Following best practices for integrating multimodal AI in applications is crucial for achieving optimal outcomes.
Exploring Real-World Case Studies of Multimodal AI
Understanding practical applications of multimodal AI enhances comprehension. Here are a few illustrative examples:
- Healthcare Diagnostics: Models are leveraging patient data - integrating text from medical records, images from X-rays, and audio notes from physicians - to offer diagnostics support and treatment suggestions.
- Retail and Marketing: By combining customer reviews (text), product images (visual), and interaction data (audio and video), businesses personalize marketing strategies and enhance customer engagement.
- Autonomous Vehicles: Autonomous systems integrate data from cameras (image), LiDAR sensors (distance), and audio inputs to navigate complex driving environments safely.
These real-world case studies of multimodal AI demonstrate how multimodal AI can transform diverse industries by combining different data types to improve decision-making and user experience.
Comparing Leading Multimodal AI Tools and Platforms
Several platforms offer robust tools for developing and deploying multimodal AI applications. Here's a comparison of some of the most prominent platforms:
Platform | Strengths | Use Cases |
|---|---|---|
Hugging Face | Extensive model library for text and images | NLP, Text Classification |
OpenAI | Advanced generative models for various tasks | Content Creation, Automation |
TensorFlow | Flexible framework for custom model training | Research, Personalized AI |
PyTorch | Dynamic computational graph for flexibility | Research, Academic Purposes |
Each platform offers unique models and capabilities, making it critical to match the tool with your particular requirements. Comparing leading multimodal AI tools and platforms is essential in identifying the best fit for your project.
Future Trends in Multimodal AI Development
As technology evolves, so do the applications and expectations of multimodal AI. Future trends include:
- Enhanced Multimodal Learning: Ongoing research is focused on improving models' ability to learn from fewer examples, making them more adaptive and efficient.
- Increased Automation: Automation in model training and deployment will continue to streamline AI integration across diverse sectors.
- Interdisciplinary Collaborations: The convergence of AI with domains like neuroscience and cognitive science could lead to even more sophisticated multimodal solutions.
- Ethics and Regulation: As AI capabilities grow, ensuring ethical deployment and navigating regulatory environments will become increasingly important.
These future trends in multimodal AI development suggest a future where multimodal AI plays an even more integral role in various industries, driving innovation and efficiency.
FAQ
- What is multimodal AI?
- Multimodal AI refers to AI systems that integrate and process multiple types of data, such as text, image, audio, and video, to perform tasks or generate insights.
- How does multimodal AI differ from traditional AI?
- Traditional AI typically focuses on one type of data, whereas multimodal AI integrates multiple data types, enabling richer and more dynamic interactions.
- What are some key applications of multimodal AI?
- It is used in areas like healthcare diagnostics, autonomous vehicles, retail personalization, and more for enhanced decision-making and user experiences.
- How can businesses benefit from multimodal AI?
- Businesses can leverage multimodal AI for improved customer interactions, personalized marketing, efficient supply chain management, and more.
- What are some challenges in implementing multimodal AI?
- Key challenges include managing computational demands, ensuring seamless integration of diverse data, and addressing ethical concerns like bias and privacy.
Common Mistakes in Multimodal AI Integration and How to Avoid Them
Integrating multimodal AI might seem like a straightforward process of connecting different data streams, but there are several common pitfalls that can derail the effort. One mistake is underestimating the complexity of data alignment. Different modalities often have varying forms and structures that need careful synchronization. For example, aligning audio timestamps with corresponding video frames must be precise. To avoid this, implement rigorous pre-processing steps to ensure data is appropriately synchronized before integration.
Another common issue is overfitting, which occurs when models learn noise instead of the actual pattern. This is tricky in multimodal settings due to the sheer amount of data. Overfitting can be mitigated by adopting techniques such as cross-validation and using dropout layers during training. Make sure to set aside substantial validation datasets that reflect real-world variability and complexity. Monitoring performance across all modalities individually will also help identify any specific areas where overfitting might occur.
Finally, many organizations overlook the importance of scalability. Initial models may work well on smaller datasets, but fall short when scaled to production size. Start by leveraging cloud platforms and technologies that support scaling, like distributed computing. Ensure your architecture is modular so that you can easily modify parts of the system without a complete overhaul as the dataset grows.
Metrics and Measuring Success in Multimodal AI Implementations
Determining the success of multimodal AI models requires unique metrics tailored to their complexity. Traditional performance metrics might only focus on a single data type, so it’s crucial to develop composite metrics that reflect the integration’s overall effectiveness. Begin by defining clear objectives for each modality separately, such as accuracy in text classification or precision in object detection in images. Then, use these to form a balanced scorecard that combines results across modalities, offering insights into the model’s comprehensive performance.
User engagement metrics can also provide valuable insights, especially when multimodal AI models are deployed in consumer-facing applications. These might include metrics like the click-through rate in recommendation systems or time spent interacting with AI-generated content. Use A/B testing to measure how user feedback might change with different AI model configurations, and adjust the algorithms accordingly to ensure they meet business goals.
Additionally, tracking the operational efficiency of the models is essential. This includes assessing the time taken for processing and response in real-time applications. Infrastructure-utilization metrics like CPU/GPU load can also highlight potential bottlenecks. Regularly review these metrics to optimize system efficiencies and fine-tune performance, especially as datasets evolve.
Step-by-Step Implementation of a Multimodal AI Project
Embarking on a multimodal AI project demands thorough planning and execution. Begin by defining the objectives of your project clearly. Identify the problem you are solving and the kinds of data you will integrate. Collect ample datasets for each modality you plan to use, ensuring they're large enough to train effective models. Annotate and preprocess these datasets to clean and structure the data appropriately, applying normalization techniques where necessary.
Next, choose suitable models for each modality. Leverage existing frameworks and pre-trained models to expedite this process. For instance, employ transformer models for text analysis, convolutional neural networks for image processing, or recurrent neural networks for audio data. Customize these models to suit your specific application needs and begin training each one independently before attempting to integrate them.
Finally, integrate these models into a cohesive system. Employ methods like late fusion, where outputs of separate models are combined to make a final prediction, or cross-modal attention mechanisms, which allow the model to weigh inputs from different modalities adaptively. Once integrated, thoroughly test the system under conditions mimicking real-world variability. Iterate on the design using feedback-driven development to refine and optimize your system before fully deploying it into your application landscape.
Related Articles
Don't miss what ships next
The daily briefing on AI & tech, straight to your inbox.
Written by
Vunsh MehtaI’m a computer science student and developer focused on AI, automation, and emerging tech. I write about AI news, tools, and trends from a practical, builder-focused perspective.